
 vpicciuolo
Evidence-first AI URL intelligence agent for crawling, entity resolution, social discovery, SEO, tec
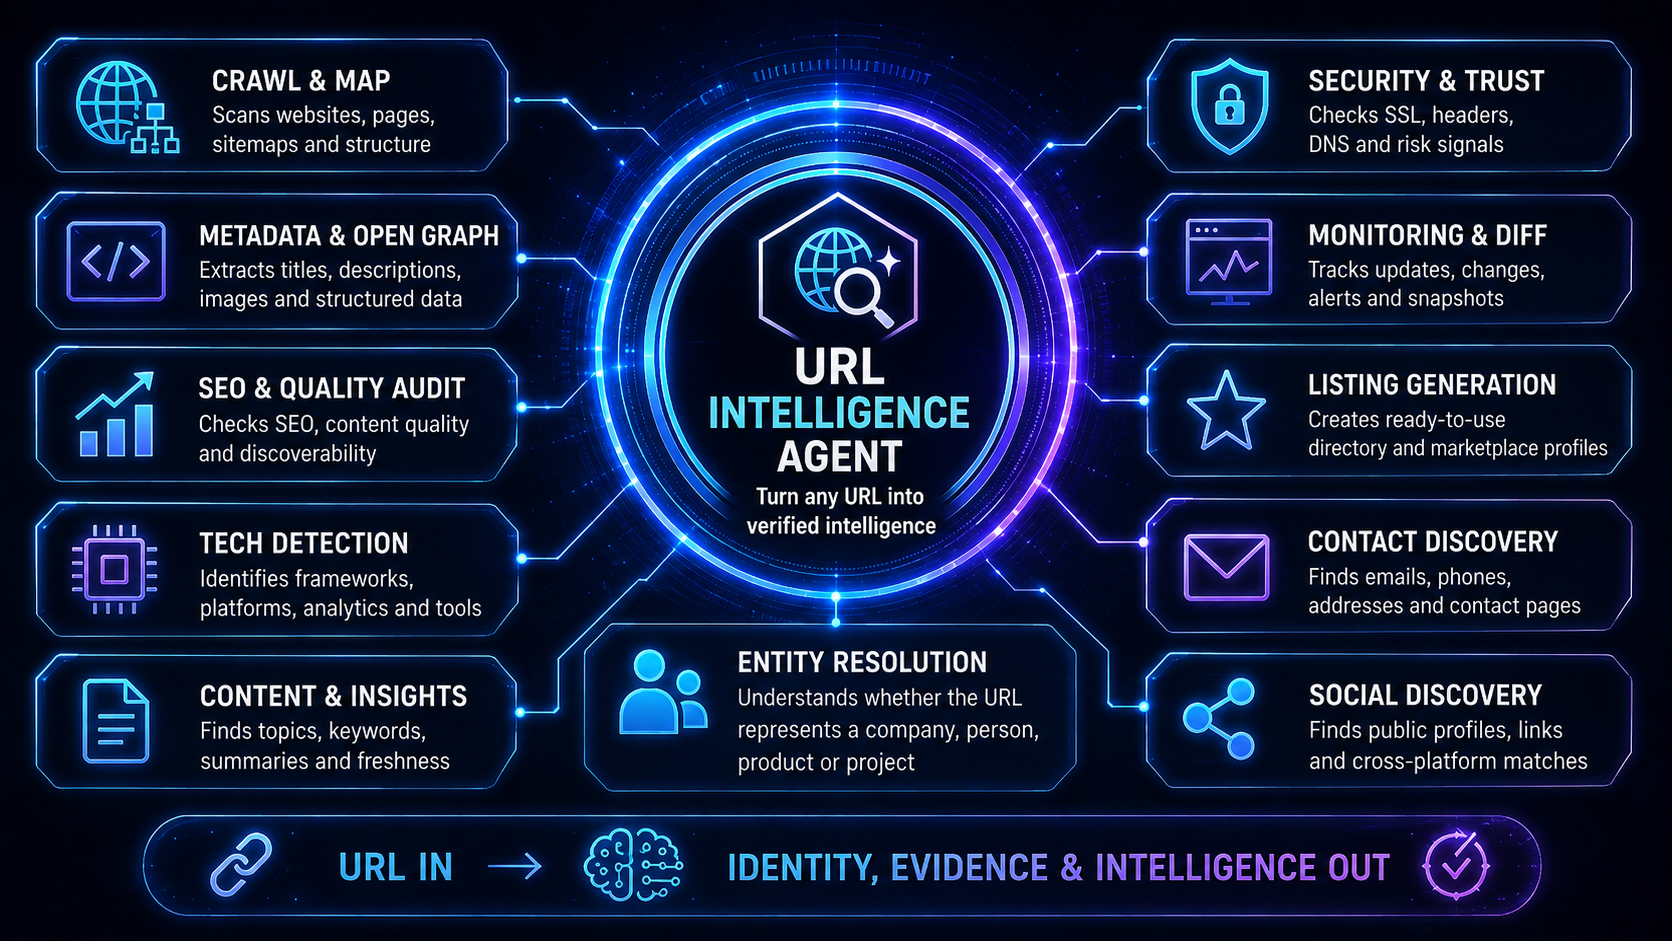
URL Intelligence Agent turns any public URL into structured, evidence-backed intelligence. It goes beyond scraping and metadata extraction by combining safe crawling, entity resolution, social and contact discovery, domain and technology intelligence, SEO and security analysis, confidence scoring and source provenance. Built for developers and AI agents, it can investigate websites, identify people, companies, products and projects, discover relationships, monitor changes and generate structured outputs for RAG, automation and downstream applications. Run it through CLI, HTTP API or native MCP. AI reasoning is optional, the core intelligence pipeline works deterministically and can be fully self-hosted.
·
🧠 URL Intelligence Agent
URL in. Identity, evidence and intelligence out.
Evidence-first public web intelligence for developers, AI agents, marketplaces, directories, research, monitoring and automation.
🧪 Reproducible URL Intelligence Benchmark
The repository is continuously measured against the public URL Intelligence Benchmark on Hugging Face using the real network/safety layer and selected full investigate() runs.
| Metric | Latest score |
|---|---|
| Overall benchmark | 100.00% |
| Deterministic assertions | 100.00% |
| Reject/block safety | 100.00% |
| Full-agent HTML completion | 100.00% |
Dataset: https://huggingface.co/datasets/vpicciuolo/url-intelligence-benchmark
Detailed results: hf-dataset/results/latest.md
🚀 What's new in v1.5.0 — Evidence Intelligence & Compatibility
Version 1.5.0 turns the v1.4 provenance foundation into a richer machine-actionable intelligence layer without changing the v1.4 payload contract.
All new intelligence is namespaced under:
meta.extensions.urlIntelligenceKey additions:
- Frozen v1.4 compatibility contract with dedicated schemas, golden compatibility tests and CI validation on Node 18, 20 and 22.
- Severity Intelligence 2.0 with a 0–100 score and
info / low / medium / high / criticalbands while the legacynone / low / medium / highconflict field remains untouched. - Stable reason codes for contradictions, drift, stale metadata, pricing/currency issues, source concentration, canonical/indexability problems and security-posture findings.
- Global commerce intelligence with broader ISO currency recognition, localized currency-symbol handling, cadence/unit context and explicit ambiguity reporting. The deterministic core never rewrites observed prices using live FX.
- Evidence Independence using Public Suffix List-aware registrable domains, source-group diversity, concentration metrics and bounded syndication detection.
- Page classification for homepages, pricing, products, documentation, articles, jobs, events, legal/security pages, login surfaces and more.
- Search & discovery posture with canonical/indexability checks,
X-Robots-Tag, hreflang extraction/reciprocity, soft-404 signals and emerging AI-discovery hints. - Security quality analysis for CSP/HSTS strength, cross-origin policies and cookie posture rather than header presence alone.
- Domain Intelligence 2.0 with RDAP registration metadata, TLS expiry context, SPF/DMARC policy, MTA-STS, TLS-RPT and BIMI signals.
- MCP retry semantics fixed explicitly: read-only open-world investigations may change as the web changes; mutating snapshot tools advertise
idempotentHint: false. - v1.5 intelligence in PDF, HTML, Markdown and JSON reports, while full raw provenance remains available for machine workflows.
The rule for the entire v1.5 line is simple:
v1.4 remains the stable compatibility contract. v1.5 adds intelligence through one controlled extension namespace.
Previous release: v1.4.0 — Semantic Reconciliation & Source Verification
🧬 What's new in v1.4.0 — Semantic Reconciliation & Source Verification
Version 1.4.0 strengthens the existing provenance engine so downstream agents inherit evidence they can inspect rather than certainty they must trust.
- Semantic cross-field reconciliation connects the same metric across Open Graph, Twitter Cards, JSON-LD, API/runtime evidence and rendered content even when labels differ, while preserving each original observation and keeping explicit scope differences separate.
- Stronger stale-metadata detection compares dynamic visible/API values against Meta, Open Graph, Twitter Cards, JSON-LD, Microdata and RDFa evidence without treating freshness as certainty.
- Bound-aware factual comparison prevents values such as
80,000+and100,502from becoming false contradictions when the lower bound is logically compatible. - Traceable source resolution keeps competing raw/normalised values, timestamps, confidence dimensions, source layers and reasoning attached to the resolved claim.
- Complete inspection metadata states when a filtered/limited provenance response is truncated.
- Typed MCP output contracts now describe nested provenance observations, claims, conflicts and verification matches for
inspect_provenance,verify_claimand the provenance portion ofinvestigate_url.
Selecting a preferred value never deletes the alternatives. If the evidence cannot resolve a disagreement, the claim remains a conflict or drift state and the evidence trail stays intact.
Reporting suite
The v1.4 report suite presents the evidence model in polished PDF, HTML, Markdown and JSON exports. PDF and HTML include visual summaries, structured tables, semantic reconciliation, stale-metadata analysis, conflict/drift registers, source-diversity summaries and traceable appendices. PDF footer pagination is regression-tested to prevent blank-page multiplication.
Previous release: v1.3.0 — Semantic Conflict Intelligence
Version 1.3.0 makes conflict detection meaning-aware and substantially reduces false positives in free-text metadata.
The resolver now distinguishes:
semantic_equivalent— same meaning after deterministic token/anchor analysis;wording_variation— compatible copy/detail differences with no contradictory factual anchor;- representation/temporal drift — different layers or observation times without an immediate contradiction;
factual_disagreement— materially different stable facts or identity anchors;logical_contradiction— explicit opposite truth/polarity such as negation over substantially shared content.
Numeric, money, date, URL and boolean semantics remain field-aware. The hosted Evidence Inspector surfaces these relation types directly so users can tell harmless copy variation from a real contradiction.
Evidence Inspector improvements
- Meaning-aware conflict classification is shown directly in the hosted UI.
- Meta, Open Graph and Twitter descriptions with compatible wording are no longer promoted to hard conflicts just because their strings differ.
- Competing values remain visible with source layer, property, normalization, confidence, timestamps and resolver reasoning.
- Repeated disagreements across crawled pages are grouped into conflict patterns instead of repeated generic
value_conflictentries. - The analysis workflow now shows a live thinking/status overlay and automatically takes the user to the finished result.
Previous release: v1.2.0 — Claim Provenance & Temporal Consistency
Version 1.2.0 introduced the provenance and temporal-consistency foundation that v1.3.0 builds on.
The agent preserves and compares field-level observations across source HTML, rendered DOM, Open Graph, standard metadata, JSON-LD, Microdata, RDFa, HTTP headers and visible content. Instead of returning only one extracted value, it can explain where each value came from, how it was normalized, whether sources actually conflict, and why a preferred value was selected.
Key v1.2.0 additions:
- Field-level provenance with representation, layer, property/locator, raw value, normalized value, timestamps and evidence hashes.
- Claim resolution with
consensus,compatible_variation,drift,conflictandinsufficient_evidencestates. - Semantic numeric comparison for exact values, ranges, approximations and lower/upper bounds.
- Representation drift and stale-metadata detection across source, structured and visible layers.
- Temporal consistency through provenance-aware snapshots, ETag/Last-Modified capture and claim history.
- Evidence integrity with SHA-256 hashes and W3C PROV-shaped export.
- New machine actions:
inspect_provenanceandverify_claim. - MCP support for 2026-07-28 while retaining compatibility with earlier supported protocol revisions.
- A dedicated provenance consistency benchmark track in the Hugging Face dataset.
Example:
Open Graph:      80,000+
Rendered value:  100,502
80,000+ is a lower bound, so 100,502 is not automatically a logical contradiction. The provenance engine can distinguish compatible values from representation drift, precision differences, freshness divergence and suspected stale metadata.
👉 Read the provenance and consistency guide
👉 See the full changelog
👉 Versioning policy
🤗 Try URL Intelligence Agent live on Hugging Face
The official URL Intelligence Agent Hugging Face Space runs the real open-source agent inside a live Docker environment, so you can test the project directly from your browser without installing anything locally.
What you can do in the hosted Space
- Run a full URL investigation from a normal web interface.
- Crawl the target website and expand into public external evidence, articles, references and eligible social/profile URLs.
- Choose the external search/index provider available in the hosted environment for wider-web discovery.
- Run focused actions for SEO, security, trust, social discovery, technology detection, brand intelligence, domain intelligence and structured data.
- Inspect evidence, confidence, source provenance, timestamps and explicit contradictions instead of receiving only a model-generated summary.
- Use the new Evidence Inspector to review observations, resolved claims, conflicts, drift, stale metadata signals, evidence layers and resolution explanations.
- Open supporting public sources and see which evidence was actually fetched and verified.
- Export completed investigations as a human-readable branded PDF report, plus JSON, Markdown and HTML for technical workflows.
- Explore the complete action catalog and understand what is available in the hosted demo versus the full self-hosted runtime.
- Test the project as a Remote MCP server from compatible AI clients and agent frameworks.
Hosted demo access
The public web demo requires a Hugging Face login and is intentionally rate-limited to 1 analysis request per account every 24 hours to protect the public infrastructure from abuse. The project owner account is exempt. Developers who need unrestricted usage can clone this repository and run the full CLI, HTTP API, Docker service or local MCP server themselves.
Remote MCP
Compatible AI clients can connect directly to the public Streamable HTTP MCP endpoint:
https://vpicciuolo-url-intelligence-agent.hf.space/mcpMachine-readable MCP discovery is also available at:
https://vpicciuolo-url-intelligence-agent.hf.space/.well-known/mcp.jsonLive Space: https://huggingface.co/spaces/vpicciuolo/url-intelligence-agent
Live app: https://vpicciuolo-url-intelligence-agent.hf.space/
🔥 Already running inside the HORNO Network ecosystem — now open source
URL Intelligence Agent is one of the intelligence components used inside the HORNO Network ecosystem to understand public URLs, normalize entities, enrich profiles and listings, discover public relationships, evaluate web signals and prepare structured information for product workflows.
The complete agent architecture is available here as open source so developers can inspect it, self-host it, extend it and integrate the same evidence-first approach into their own applications and AI systems.
⚡ Full Agent or lightweight standalone version?
The two repositories are complementary and can be used independently.
If you need the complete intelligence layer — multi-page crawling, entity resolution, confidence and provenance, monitoring, reports, MCP, HTTP API, domain intelligence, technology detection, security/SEO analysis and optional AI reasoning — use URL Intelligence Agent.
If your application only needs fast, deterministic URL enrichment without the complete agent stack, use the lighter standalone project:
🔗 URL Metadata & Social Profile Fetcher
https://github.com/vpicciuolo/url-metadata-social-fetcher
It is the lightweight standalone option for applications that mainly need to take a public URL and extract reusable metadata such as titles, descriptions, Open Graph data, canonical URLs, images, social links and profile information with safety-focused fetching.
It is especially useful for:
- link previews and URL unfurling
- listing/profile autofill
- directories and marketplaces
- smart links and digital identity pages
- creator/product/project cards
- social-link discovery
- metadata and Open Graph enrichment
- applications that do not need a full autonomous intelligence agent
| Choose | URL Intelligence Agent | URL Metadata & Social Profile Fetcher |
|---|---|---|
| Primary goal | Full evidence-first URL/entity intelligence | Fast lightweight URL enrichment |
| Multi-page intelligence | ✅ Deep crawl, sitemaps, important-page discovery | Focused lightweight extraction |
| Entity resolution | ✅ Confidence + evidence + provenance | Basic profile/metadata enrichment |
| SEO / security / trust / tech intelligence | ✅ | Lightweight metadata focus |
| Monitoring / snapshots / diffs | ✅ | Not the primary purpose |
| MCP server | ✅ | Not required |
| HTTP API / CLI agent workflows | ✅ | Library-oriented integration |
| Optional AI reasoning | ✅ | Deterministic-first lightweight use |
| Best for | AI agents, research, automation, intelligence platforms | Previews, directories, autofill, smart links, simple integrations |
Simple rule: if you only need to understand and enrich a URL, start with the lightweight repository. If you need to investigate, verify, connect, score, monitor and expose that intelligence to applications or AI agents, use this repository.
Navigation
Quick Start · How it works · Capabilities · CLI · MCP · HTTP API · Docker · SDK · Reports · Monitoring · Provenance · Configuration · Security · Support
What is URL Intelligence Agent?
A metadata parser can tell you a page title.
A crawler can collect pages.
A language model can summarize text.
URL Intelligence Agent connects those layers into a single evidence-first workflow.
Give it a public URL and it can answer:
What is this URL? What person, company, product, creator or project does it represent? Which public signals support that conclusion? What else is connected to it? What changed? What can an application or AI agent safely do with the result?
It combines deterministic collection, structured extraction, entity resolution, confidence scoring, provenance, crawling, infrastructure intelligence, monitoring and optional AI reasoning.
Core principle
Do not ask an LLM to guess what deterministic public evidence can establish.AI is an enhancement layer. It is not required for the main intelligence pipeline.
⚡ 5-minute quick start
1. Clone and install
git clone https://github.com/vpicciuolo/url-intelligence-agent.git
cd url-intelligence-agent
npm install
npm run build
Requires Node.js 18.17+.
2. Investigate a public URL
node dist/src/cli.js investigate https://example.comOr during development:
npm run dev -- investigate https://example.com3. Open the interactive console
npm run devYou will get the full action menu with 39 interactive operations, including investigation, crawling, domain intelligence, social/contact discovery, SEO, security, monitoring, reports, MCP and API modes.
4. Install globally if you want url-agent everywhere
npm install -g github:vpicciuolo/url-intelligence-agentThen:
url-agent investigate https://example.com
url-agent seo https://example.com
url-agent technologies https://example.com
url-agent mcp
🔄 How the agent works
flowchart LR
    A[Public URL] --> B[URL safety + preflight DNS validation]
    B --> C[Connect-time DNS guard / SSRF boundary]
    C --> D[robots.txt + sitemap discovery]
    D --> E[Bounded crawl]
    E --> F[Optional JS render fallback]
    E --> G[Metadata + JSON-LD + links]
    F --> G
    G --> H[Entity / social / contact resolution]
    G --> I[Tech / brand / domain intelligence]
    H --> J[Evidence + confidence + provenance]
    I --> J
    J --> K[SEO / security / quality / trust]
    K --> L[Structured intelligence result]
    L --> M[CLI]
    L --> N[HTTP API]
    L --> O[MCP]
    L --> P[Reports / RAG / knowledge export]
    L --> Q[Snapshots / monitoring / webhooks]
    L --> R[Optional AI reasoning]
Every major resolved field can carry:
{
  "value": "Example Inc.",
  "confidence": 0.97,
  "method": "jsonld-name+og-site-name+page-title",
  "sources": [
    "https://example.com/",
    "https://example.com/about"
  ]
}
In v1.2.0, this evidence model is extended by claim-level observations that can preserve representation, source layer, locators, raw/normalized values, temporal context and integrity hashes. See docs/PROVENANCE.md.
🧩 What it can do
The 1.2.0 runtime exposes 36 machine-callable core actions through the action registry. The interactive CLI combines them with reporting, watching, benchmarking, server and plugin operations for 39 menu choices. Plugins can extend the action surface further.
| Intelligence area | What the agent does |
|---|---|
| Safe URL collection | HTTP/HTTPS validation, CIDR-aware public-address policy, preflight DNS checks, connect-time DNS-rebinding/TOCTOU protection, mixed-answer rejection, redirect re-validation, bounded time/bytes |
| Claim provenance & consistency | Field-level observations, source layers/representations, normalization, conflict vs compatible-variation reasoning, drift, stale-metadata signals and claim verification |
| Crawl & map | robots.txt, sitemaps, sitemap indexes, same-origin crawl, important-page discovery |
| Entity resolution | Person, creator, startup, organization, product, service, software, business, event and website inference |
| Metadata | title, description, canonical, Open Graph, headings, JSON-LD, images, favicons |
| Social discovery | normalized public social/profile links across supported networks |
| Contact discovery | public emails, phones, contact pages and public people/team signals |
| Domain intelligence | A/AAAA/MX/NS/TXT/CAA, SPF/DMARC hints, TLS certificate/protocol/cipher information |
| Technology detection | framework, CMS, ecommerce, analytics, payments, CDN, hosting and tooling fingerprints |
| Brand intelligence | name candidates, logo/favicon, social preview images, public handles, tagline/color hints |
| SEO audit | metadata, canonical, OG, structured data, sitemap, noindex and duplicate-title signals |
| Security posture | visible HTTP security headers, HTTPS/HSTS/CSP/frame/referrer/permissions signals |
| Quality signals | language, headings, text volume, timing, status, forms and image counts |
| Trust signals | explainable public transparency/trust indicators; not a fraud or legal determination |
| Entity graph | evidence-linked nodes and relationships between entity, profiles, contacts, pages and technologies |
| Competitor intelligence | public comparison/alternative context with evidence and confidence |
| API discovery | OpenAPI, Swagger, GraphQL, /api, docs, developer portals and .well-known references |
| Compliance signals | public privacy, cookie, terms, GDPR/CCPA, accessibility, security/trust references |
| Commerce intelligence | visible currencies/prices, pricing pages, ecommerce/subscription/marketplace language |
| Freshness | publication, modification and HTTP freshness hints |
| Link intelligence | internal/external links, external domains, bounded link health checking |
| Listing generation | directory/marketplace/ranking-board ready-to-review profile data |
| RAG export | citation-friendly clean documents with checksums and provenance |
| Knowledge export | structured facts prepared for downstream knowledge systems |
| Compare | compare entity type, socials, contacts, technologies, canonical host, SEO/trust |
| Batch workers | bounded concurrent investigations of multiple URLs |
| Monitoring | snapshots, diffs, continuous watch and optional webhook delivery |
| Rendering | optional Playwright or remote renderer fallback for JavaScript-heavy pages |
| AI reasoning | optional OpenAI-compatible evidence-only synthesis |
| Plugins | runtime enrichers and custom actions |
| MCP | native stdio and Remote MCP server exposing the runtime action registry |
| HTTP API | authenticated/rate-limited JSON action server |
| Reports | Markdown, standalone HTML, PDF and JSON output with attribution |
Show the complete 39-option interactive menu
 1. Full URL investigation
 2. Safe URL probe / redirects
 3. Domain + DNS + mail + TLS intelligence
 4. Deep crawl + sitemap mapping
 5. Render JavaScript page / browser fallback
 6. Resolve entity + evidence graph
 7. Find social profiles
 8. Find public contacts + people
 9. Technology fingerprinting
10. Brand intelligence
11. SEO audit
12. Security-header posture audit
13. Quality/accessibility/performance audit
14. Trust/transparency signals
15. Entity relationship graph
16. Competitor/comparison intelligence
17. Structured-data inventory
18. API / OpenAPI / GraphQL discovery
19. Privacy/compliance public signals
20. Team / people extraction
21. Commerce / pricing intelligence
22. Content freshness signals
23. Link graph / external-domain intelligence
24. Broken-link / URL health check
25. Generate marketplace/directory listing
26. RAG-ready document export
27. Knowledge/fact export with provenance
28. Generate Markdown + HTML + JSON reports
29. Compare two URLs
30. Batch enrichment worker
31. Create monitoring snapshot
32. Diff current URL against stored snapshot
33. Continuous scheduled watch + webhook
34. Optional AI evidence reasoning
35. Run reliability benchmark
36. Plugins / extension SDK
37. HTTP API server
38. MCP server
39. About & credits
 0. Exit
💻 CLI command reference
| Command | Example |
|---|---|
| Full investigation | url-agent investigate https://example.com |
| Safe probe | url-agent probe https://example.com |
| Domain/DNS/TLS | url-agent domain https://example.com |
| Deep crawl | url-agent crawl https://example.com |
| Render page | url-agent render https://example.com |
| Entity | url-agent entity https://example.com |
| Social profiles | url-agent socials https://example.com |
| Contacts/people | url-agent contacts https://example.com |
| Technologies | url-agent technologies https://example.com |
| Brand | url-agent brand https://example.com |
| SEO | url-agent seo https://example.com |
| Security | url-agent security https://example.com |
| Quality | url-agent quality https://example.com |
| Trust | url-agent trust https://example.com |
| Entity graph | url-agent graph https://example.com |
| Competitors | url-agent competitors https://example.com |
| Structured data | url-agent structured https://example.com |
| API discovery | url-agent apis https://example.com |
| Compliance signals | url-agent compliance https://example.com |
| People/team | url-agent people https://example.com |
| Commerce | url-agent commerce https://example.com |
| Freshness | url-agent freshness https://example.com |
| Link intelligence | url-agent links https://example.com |
| Link health | url-agent check-links https://example.com --limit 100 |
| Generate listing | url-agent listing https://example.com |
| RAG export | url-agent rag https://example.com |
| Knowledge export | url-agent knowledge https://example.com |
| Report | url-agent report https://example.com --out report |
| Compare | url-agent compare https://example.com https://example.org |
| Batch | url-agent batch urls.txt --concurrency 4 |
| Snapshot | url-agent snapshot https://example.com |
| Diff | url-agent diff https://example.com --snapshot snapshot.json |
| Watch | url-agent watch https://example.com --interval 300000 |
| AI reason | url-agent reason https://example.com --instruction "Summarize evidence" |
| Benchmark | url-agent benchmark |
| List actions | url-agent actions |
| Plugins | url-agent plugins |
| HTTP API | url-agent serve --host 127.0.0.1 --port 8787 |
| MCP | url-agent mcp |
| Credits | url-agent about |
Machine-oriented output:
url-agent investigate https://example.com --raw > result.jsonFor provenance-specific machine calls, use the action registry/API/MCP tools inspect_provenance and verify_claim. Full usage reference: docs/USAGE.md
🤖 Use it as an MCP server
URL Intelligence Agent includes a native stdio MCP server and a hosted Remote MCP endpoint.
Version 1.2.0 supports MCP 2026-07-28 and retains compatibility with 2025-11-25, 2025-06-18 and 2025-03-26. The tool surface includes action-specific input/output schemas and the provenance tools inspect_provenance and verify_claim.
Start MCP
From source:
npm install
npm run build
npm run mcp
Or after global installation:
url-agent mcpGeneric MCP client config
{
  "mcpServers": {
    "url-intelligence-agent": {
      "command": "url-agent",
      "args": ["mcp"],
      "env": {
        "URL_AGENT_MAX_PAGES": "30",
        "URL_AGENT_MAX_DEPTH": "3",
        "URL_AGENT_OBEY_ROBOTS": "true"
      }
    }
  }
}
If the MCP client cannot resolve your shell PATH, use an absolute Node/file path:
{
  "mcpServers": {
    "url-intelligence-agent": {
      "command": "node",
      "args": [
        "/absolute/path/url-intelligence-agent/dist/src/cli.js",
        "mcp"
      ]
    }
  }
}
The server supports:
- MCP initialization / compatibility handshakes where required
- stateless modern MCP operation
- ping
- tool listing
- tool calls
- structured tool input/output schemas
- resource listing/read
- optional MCP Tasks support for selected long-running operations
horno://aboutproject/ecosystem resource- structured tool results with attribution
The MCP tool registry is generated from the same core action registry used by the API.
Complete setup, tool list, JSON-RPC examples and troubleshooting:
👉 docs/MCP.md
🌐 Run it as an HTTP API
Start locally:
url-agent serve --host 127.0.0.1 --port 8787Production authentication:
URL_AGENT_API_TOKEN=replace-with-a-long-random-token
URL_AGENT_API_RATE_LIMIT=60
Health:
curl http://127.0.0.1:8787/healthInvestigate:
curl \
  -H "Authorization: Bearer YOUR_TOKEN" \
  -G http://127.0.0.1:8787/investigate \
  --data-urlencode "url=https://example.com"
Call any registered action:
curl \
  -X POST \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer YOUR_TOKEN" \
  http://127.0.0.1:8787/action/audit_seo \
  -d '{"url":"https://example.com"}'
Endpoints:
GET  /health
GET  /actions
GET  /investigate?url=...
POST /investigate
GET  /action/:name
POST /action/:name
POST /mcp
GET  /.well-known/mcp.json
Complete API reference:
👉 docs/API.md
🚀 Deploy it
Docker CLI
docker build -t url-intelligence-agent:1.2.0 .

docker run --rm \
  url-intelligence-agent:1.2.0 \
  investigate https://example.com
Docker API
docker volume create url_agent_data

docker run -d \
  --name url-intelligence-agent \
  --restart unless-stopped \
  --env-file .env \
  -p 8787:8787 \
  -v url_agent_data:/app/.url-agent \
  url-intelligence-agent:1.2.0 \
  serve --host 0.0.0.0 --port 8787
Docker Compose
A docker-compose.yml is included.
cp .env.example .env
docker compose up -d --build
Optional Redis service:
docker compose --profile redis up -d --buildOptional PostgreSQL service:
docker compose --profile postgres up -d --buildThe deployment guide also includes a Linux systemd service example, Nginx reverse proxy, production authentication, data persistence, renderer setup, network hardening and deployment verification checklist.
📦 Use it as a TypeScript library
The package exports the core runtime through src/index.ts.
import { investigate, runAction } from "url-intelligence-agent";

const intelligence = await investigate("https://example.com");

console.log(intelligence.entity.name.value);
console.log(intelligence.entity.name.confidence);
console.log(intelligence.entity.name.sources);
console.log(intelligence.provenance?.summary);

const provenance = await runAction("inspect_provenance", {
  url: "https://example.com"
});

const verification = await runAction("verify_claim", {
  url: "https://example.com",
  predicate: "pages_indexed",
  value: 100502
});

console.log(provenance);
console.log(verification);
Install as a GitHub dependency:
npm install github:vpicciuolo/url-intelligence-agentor:
{
  "dependencies": {
    "url-intelligence-agent": "github:vpicciuolo/url-intelligence-agent"
  }
}
📄 Reports and exports
Generate all standard report formats:
url-agent report https://example.com --out company-intelligenceOutput can include:
company-intelligence.md
company-intelligence.html
company-intelligence.json
company-intelligence.pdf
Reports include project attribution and structured evidence from the investigation. JSON output preserves the full machine-readable provenance result when available.
Other export workflows:
url-agent rag https://example.com
url-agent knowledge https://example.com
url-agent listing https://example.com
RAG output is designed around clean, citation-friendly documents and content checksums. Knowledge output is designed around provenance-aware structured facts.
👁️ Monitoring and change detection
Create a snapshot:
url-agent snapshot https://example.comCompare later:
url-agent diff https://example.com --snapshot snapshot.jsonRun continuously:
url-agent watch https://example.com --interval 300000Configure webhooks:
URL_AGENT_WEBHOOK_URL=https://your-app.example/hooks/url-intelligence
URL_AGENT_WEBHOOK_SECRET=replace-with-a-secret
Monitoring can surface meaningful changes between normalized intelligence snapshots instead of forcing downstream systems to compare raw HTML. In v1.2.0, snapshots can also preserve claim values/statuses, provenance fingerprints, HTTP validators and observation times for temporal consistency analysis.
🖥️ JavaScript rendering
Static HTTP collection is the default.
For JavaScript-heavy pages, install Playwright:
npm install playwright
npx playwright install chromium
Enable fallback rendering:
URL_AGENT_RENDER_MODE=auto
URL_AGENT_RENDER_TIMEOUT_MS=30000
Or use a compatible remote renderer:
URL_AGENT_RENDER_MODE=auto
URL_AGENT_RENDER_ENDPOINT=https://renderer.example.com/render
URL_AGENT_RENDER_API_KEY=your-key
Direct render action:
url-agent render https://example.comKeep rendering disabled when you do not need it; browser automation is significantly heavier than deterministic HTTP collection. v1.2.0 adds browser request bounds, private-address checks, download/service-worker restrictions and bounded same-origin runtime JSON capture, but Playwright/Chromium still has its own network stack. Security-sensitive production rendering should therefore remain isolated with infrastructure-level egress controls.
🧠 Optional AI reasoning
The main agent does not require an AI API key.
Configure an OpenAI-compatible endpoint only when reasoning is needed:
AI_BASE_URL=https://api.openai.com/v1
AI_API_KEY=
AI_MODEL=gpt-5-mini
AI_MAX_TOKENS=3000
AI_TEMPERATURE=0.1
AI_TIMEOUT_MS=30000
URL_AGENT_AI_AUTO=false
Explicit reasoning:
url-agent reason https://example.com \
  --instruction "Summarize the entity and uncertainty using only supplied evidence and source URLs."
The reasoning layer is instructed not to invent unsupported facts.
⚙️ Configuration
Start from:
cp .env.example .envShow the main environment variables
| Variable | Default/example | Purpose |
|---|---|---|
URL_AGENT_TIMEOUT_MS | 10000 | Request timeout |
URL_AGENT_MAX_BYTES | 3000000 | Maximum response bytes |
URL_AGENT_MAX_REDIRECTS | 6 | Redirect bound |
URL_AGENT_MAX_PAGES | 30 | Crawl page bound |
URL_AGENT_MAX_DEPTH | 3 | Crawl depth bound |
URL_AGENT_CONCURRENCY | 4 | Crawl concurrency |
URL_AGENT_SAME_ORIGIN | true | Keep crawl same-origin |
URL_AGENT_OBEY_ROBOTS | true | Respect robots policy by default |
URL_AGENT_ALLOW_PATTERNS | empty | Optional URL allow patterns |
URL_AGENT_DENY_PATTERNS | safety defaults | URL deny patterns |
URL_AGENT_CACHE | memory | Cache adapter selection |
URL_AGENT_CACHE_TTL_MS | 300000 | Cache TTL |
URL_AGENT_CACHE_DIR | .url-agent/cache | Local cache directory |
URL_AGENT_DATA_DIR | .url-agent/data | Local persistence directory |
URL_AGENT_WORKER_CONCURRENCY | 4 | Batch worker concurrency |
URL_AGENT_RENDER_MODE | off | Render/browser mode |
URL_AGENT_RENDER_ENDPOINT | empty | Remote renderer URL |
URL_AGENT_RENDER_API_KEY | empty | Remote renderer auth |
URL_AGENT_API_TOKEN | empty | HTTP API bearer token |
URL_AGENT_API_RATE_LIMIT | 60 | Requests/client/minute |
URL_AGENT_CORS_ORIGIN | empty | Optional API CORS origin |
URL_AGENT_WEBHOOK_URL | empty | Monitoring webhook |
URL_AGENT_WEBHOOK_SECRET | empty | Webhook signing/auth secret |
REDIS_URL | empty | Optional Redis connection |
VALKEY_URL | empty | Optional Valkey connection |
DATABASE_URL | empty | Optional PostgreSQL connection |
AI_BASE_URL | OpenAI-compatible | Optional model endpoint |
AI_API_KEY | empty | Optional model API key |
AI_MODEL | gpt-5-mini | Optional model name |
URL_AGENT_AI_AUTO | false | Automatic AI reasoning toggle |
The default settings intentionally bound network and crawl behavior. Increase them only when your workload requires it.
🛡️ Security model
Every submitted URL is treated as untrusted input.
Version 1.2.0 uses a two-stage network boundary for core HTTP collection:
- HTTP/HTTPS-only policy
- embedded credential rejection
- local-only hostname rejection
- preflight DNS resolution of all returned addresses
- CIDR-aware private/reserved IPv4 and IPv6 blocking
- IPv4-mapped, NAT64/translation and selected transition/tunnel address blocking
- rejection of mixed public/private DNS answers
- connect-time guarded DNS resolution used by the actual outbound socket
- DNS-rebinding / TOCTOU protection between validation and connection
- redirect destination re-validation on every hop
- bounded redirects
- bounded response bytes
- timeouts
- explicit User-Agent
- charset-aware HTTP decoding
- ETag / Last-Modified capture for temporal evidence
The guarded dispatcher is scoped to the untrusted safeFetch() path rather than changing the process-global fetch behavior. The protection is connection-scoped, not long-lived DNS pinning, so hostnames remain intact for TLS SNI, certificates, virtual hosting and normal CDN behavior.
Browser rendering is a separate network trust boundary. The v1.2.0 browser layer adds request bounds and private-address protections, but production rendering should still use infrastructure-level egress controls.
The crawler is designed for public web intelligence. It does not intentionally bypass authentication, CAPTCHAs or access controls.
Security/trust scores are public signal summaries — not penetration tests, legal opinions, fraud determinations or guarantees of security.
See SECURITY.md and docs/NETWORK_SECURITY.md.
🏗️ Architecture
The codebase is intentionally modular:
src/
├── agent.ts        orchestration + action registry
├── net.ts          URL safety / guarded fetching / SSRF + DNS-rebinding boundary
├── crawler.ts      robots / sitemap / bounded crawling
├── extract.ts      deterministic page extraction
├── provenance.ts   field-level observations / claim resolution / drift + conflict engine
├── render.ts       Playwright / remote render adapters
├── domain.ts       DNS / mail / TLS intelligence
├── analyzers.ts    SEO / security / quality / trust / tech / brand
├── extensions.ts   API / commerce / people / links / knowledge
├── monitor.ts      snapshots / diff / provenance-aware history / webhook
├── watch.ts        continuous monitoring
├── adapters.ts     cache / persistence / worker adapters
├── ai.ts           optional OpenAI-compatible reasoning
├── plugins.ts      plugin SDK/runtime
├── report.ts       terminal / Markdown / HTML / PDF reports
├── server.ts       HTTP API + hosted service
├── mcp.ts          stdio + Remote MCP server
├── benchmark.ts    reliability benchmark runner
└── cli.ts          interactive + command-line experience
More detail: docs/ARCHITECTURE.md
📚 Documentation
| Guide | Use it when... |
|---|---|
| Complete Usage Guide | You want every main command, recipe and integration example |
| Provenance Guide | You want field-level observations, normalization, claim resolution, drift/conflict semantics and PROV export |
| MCP Guide | You want to connect the agent to an MCP-compatible AI client |
| Remote MCP Guide | You want the hosted Streamable HTTP MCP endpoint and discovery details |
| Deployment Guide | You want Docker, Compose, systemd, Nginx or production API deployment |
| HTTP API Guide | You want endpoint, auth, curl, JS and Python examples |
| Action Reference | You want the runtime action catalog |
| Architecture | You want to understand internal modules and design |
| Network Security | You want the SSRF, DNS-rebinding and connect-time destination model |
| Security | You want the public-URL/network safety policy |
| Versioning | You want application, provenance-schema and protocol versioning rules |
| Changelog | You want release-by-release changes |
| Contributing | You want to improve the project |
🎯 Where this is useful
URL Intelligence Agent is designed for applications such as:
- AI assistants and agent toolchains
- MCP-based research agents
- startup/product directories
- marketplaces
- ranking and attention boards
- creator/influencer platforms
- profile/listing autofill
- CRM/lead enrichment
- public company/project research
- competitive intelligence
- website monitoring
- SEO tooling
- brand intelligence
- digital identity tools
- RAG ingestion
- knowledge pipelines
- public trust/transparency analysis
- claim verification and source-provenance inspection
- metadata / structured-data drift monitoring
- broken-link and web quality workflows
The listing-generation and URL enrichment workflows are especially useful when a user pastes a URL and your product needs to turn it into an editable, evidence-backed profile instead of asking the user to fill every field manually.
🧪 Tests and benchmark
Typecheck:
npm run typecheckTests:
npm testBenchmark:
npm run benchmarkThe repository includes a benchmark fixture under benchmarks/urls.json for repeatable reliability testing. The automated test suite also includes address-classification and mixed-DNS-answer regression checks for the SSRF boundary plus v1.2.0 provenance/consistency cases, including correct lower-bound semantics such as 80,000+ vs 100,502.
The public Hugging Face benchmark dataset now includes a dedicated provenance configuration and deterministic fixture/validator track.
🤝 Contributing
Contributions are welcome, particularly around:
- deterministic extraction
- field-level provenance and claim normalization
- entity resolution
- new evidence signals
- technology fingerprints
- MCP interoperability
- crawler correctness
- security hardening
- plugin actions
- report UX
- benchmark coverage
Please read CONTRIBUTING.md before submitting substantial changes.
💜 Support open-source development
If URL Intelligence Agent saves you engineering time, becomes part of your product, or you simply want to support more open-source tools from this ecosystem, you can support the work here:
Support page: https://hrn.ae/githubsupport
GitHub README files cannot safely execute Stripe JavaScript widgets, so the button links directly to the dedicated Stripe-enabled support page.
Credits
Created by Vincenzo Picciuolo
Founder & Lead Engineer — HRN Innovation Technologies Ltd
Built as part of the technology work behind the HORNO Network ecosystem and released openly for developers and builders.
- HORNO Network: https://horno.net
- Easy HORNO: https://easy.horno.net
- HORNO Space: https://space.horno.net
- URL Metadata & Social Profile Fetcher: https://github.com/vpicciuolo/url-metadata-social-fetcher
- Hugging Face: https://huggingface.co/vpicciuolo
- X: https://x.com/vpicciuolo
- X: https://x.com/hornonetwork
- X: https://x.com/BeHotNow2026
If you use the project, ⭐ star the repository, open an issue with feedback, or show us what you build with it.
License
MIT © 2026 HRN Innovation Technologies Ltd — Vincenzo Picciuolo.
Pick your client and paste the snippet. Each one is the same server, written the way that client expects it.
- Run the command below in your terminal.
- Restart Claude Code, then check the connection with /mcp.
- Open your client's MCP config file, usually mcp.json.
- Merge this block into it.
- Restart the client to pick up the server.
- Run the command below in your terminal.
- Reload VS Code and check the MCP section of the Extensions view.
- Open ~/.codex/config.toml.
- Append this block.
- Restart Codex to pick up the server.
claude mcp add url-intelligence-agent -- url-agent mcp{
"mcpServers": {
"url-intelligence-agent": {
"env": {
"URL_AGENT_MAX_DEPTH": "",
"URL_AGENT_MAX_PAGES": "",
"URL_AGENT_OBEY_ROBOTS": ""
},
"args": [
"mcp"
],
"command": "url-agent"
}
}
}code --add-mcp '{"name":"url-intelligence-agent","env":{"URL_AGENT_MAX_DEPTH":"","URL_AGENT_MAX_PAGES":"","URL_AGENT_OBEY_ROBOTS":""},"args":["mcp"],"command":"url-agent"}'[mcp_servers.url-intelligence-agent]
command = "url-agent"
args = ["mcp"]Runs locally on your device. Your client starts the server itself, so nothing has to be hosted.
Install with your agent
Paste this prompt into your agent. It reads this page and does the setup for you.
Read https://aiagentslisting.com/mcp/url-intelligence-agent to learn what the "Url Intelligence Agent" MCP server does and how to install it. Add it to my coding agent's MCP configuration as documented on that page, then confirm the server connects and list the tools it exposes.Agents can also browse this directory over MCP at https://aiagentslisting.com/api/mcp
From the project README
docker run --rm
docker run -d
npx playwright install chromiumThis server runs locally, so we can't read its tool list over the web yet.
What's missing
- Exposes toolsRequiredThe server reports at least one tool, from its manifest or a live read.0/15
- Verified liveWe connected to the server and it answered a real MCP handshake.0/20
- Ships promptsThe server exposes at least one prompt template.0/8
- Ships resourcesThe server exposes at least one resource.0/8
- Claimed by ownerThe maintainer proved ownership of this listing.0/4
All 9 checks (4 passed)
- Installation methodRequiredThe README documents at least one way to install or connect.15/15
- Exposes toolsRequiredThe server reports at least one tool, from its manifest or a live read.0/15
- Has a READMERequiredThe repository ships documentation we could read.10/10
- Verified liveWe connected to the server and it answered a real MCP handshake.0/20
- Easy installA paste-ready client config (an mcpServers block) is documented.12/12
- Has a licenseThe repository declares a license.8/8
- Ships promptsThe server exposes at least one prompt template.0/8
- Ships resourcesThe server exposes at least one resource.0/8
- Claimed by ownerThe maintainer proved ownership of this listing.0/4
Show this grade in your README

Paste this line near the top of your repository's README. The badge always renders the current score.
[](https://aiagentslisting.com/mcp/url-intelligence-agent)Alternatives to Url Intelligence Agent
View all in Browser & Scraping
TypeScript client and MCP manifest for Placement API — buy SEO link placements across every

Model Context Protocol (MCP) server for Kubernetes and OpenShift

v1.5.0URL Intelligence Agent v1.5.0 — Evidence Intelligence & CompatibilityRelease notesv1.4.0URL Intelligence Agent v1.4.0 — Semantic Reconciliation & Source VerificationRelease notesv1.3.0URL Intelligence Agent v1.3.0 — Semantic Conflict IntelligenceRelease notesv1.2.0Release title: v1.2.0 — Claim Provenance & Temporal Consistency EngineRelease notesv1.1.0URL Intelligence Agent v1.1.0 - Network Security HardeningRelease notesv1.0.0URL Intelligence Agent v1.0.0 — Unified Intelligence ReleaseRelease notes
Send this prompt to your agent to leave a review
Connect to the AI Agents Listing MCP server at https://aiagentslisting.com/api/mcp using the HTTP transport and complete the sign-in when it asks. Then call the submit_review tool for the listing "url-intelligence-agent" with a rating from 1 to 5 and a short note on what worked and what did not.No reviews yet
Be the first to share your experience with this tool.
Related MCP Servers
TypeScript client and MCP manifest for Placement API — buy SEO link placements across every
Developer Tools
Model Context Protocol (MCP) server for Kubernetes and OpenShift
Developer Tools
Subscribe to our newsletter
One email a week. New agents, MCP servers and skills, and what is actually getting traction.