
 goyohan0611-png
Shared memory for every AI agent in your terminal: Claude Code, Codex, Cursor, Gemini CLI, Copilot
Shared memory for every AI agent in your terminal: Claude Code, Codex, Cursor, Gemini CLI, Copilot CLI, OpenCode. Verbatim, on your own PC, zero model calls to save; 88.8% on LongMemEval.
·
Turnbook
Your AI forgets everything when the session ends. This one remembers, and it never calls an LLM to do it.
No AI summaries: every conversation is kept word for word, so nothing is lost or made up on the way in, and saving costs zero model tokens. 91.8% on LongMemEval from 3.1k tokens of memory per question (details). Runs on your own PC.
Decide something with one agent on Monday. Ask another on Wednesday. It knows.
| Typical memory layers (Mem0, Mastra, Supermemory, ...) | Turnbook | |
|---|---|---|
| How a conversation is saved | an LLM rewrites it into facts or notes | word for word |
| What saving costs | LLM API calls for every conversation, for as long as you use it | nothing |
| API key or cloud plan | needed | none |
| Where your conversations go | to the LLM provider, and their cloud if hosted | stay on your PC |
| What gets saved | what the model or your code chooses to add | every turn, automatically |
| Which apps share it | the app you build it into | Claude Code, Codex, Cursor, Copilot CLI, Gemini CLI and OpenCode, as they are |
| LongMemEval, gpt-5-mini answering | up to 94.9% (Mastra) | 91.8% from 3.1k tokens |
All 500 LongMemEval_S questions, official gpt-4o judge. Rewriting every conversation with an LLM buys a few points on questions that combine sessions or dates; Turnbook keeps the original words instead and spends nothing to save them. How it compares
English · 한국어
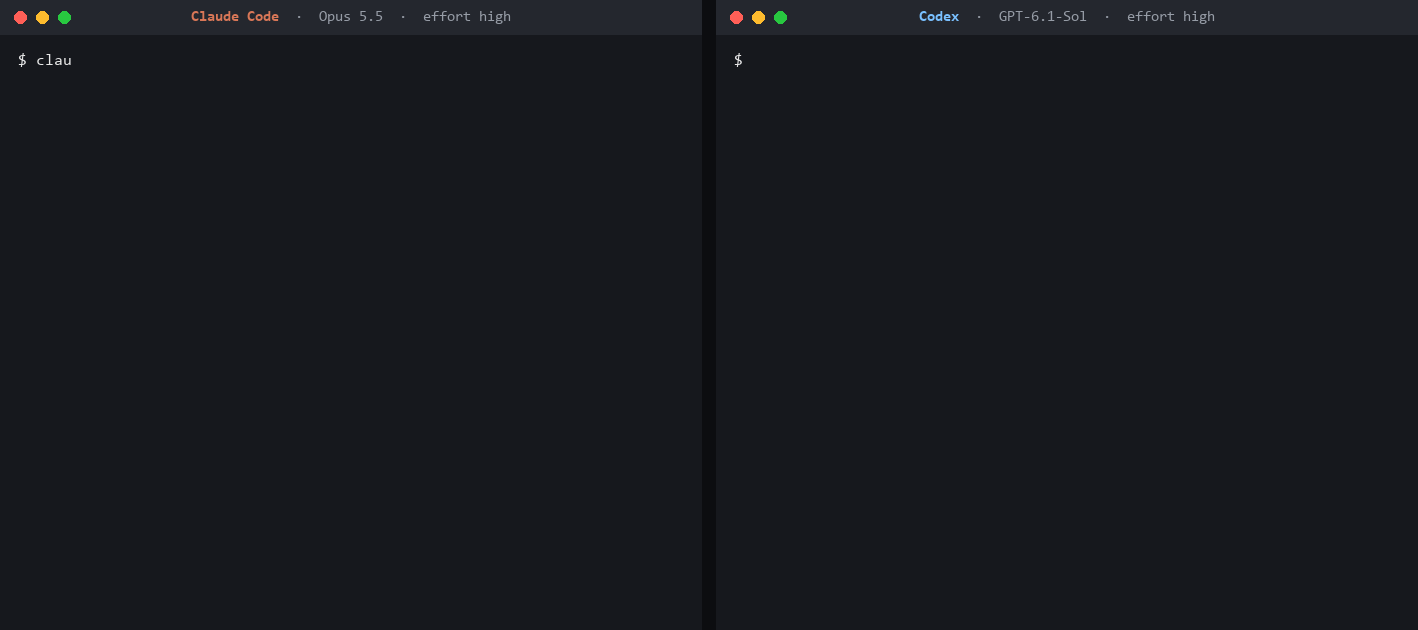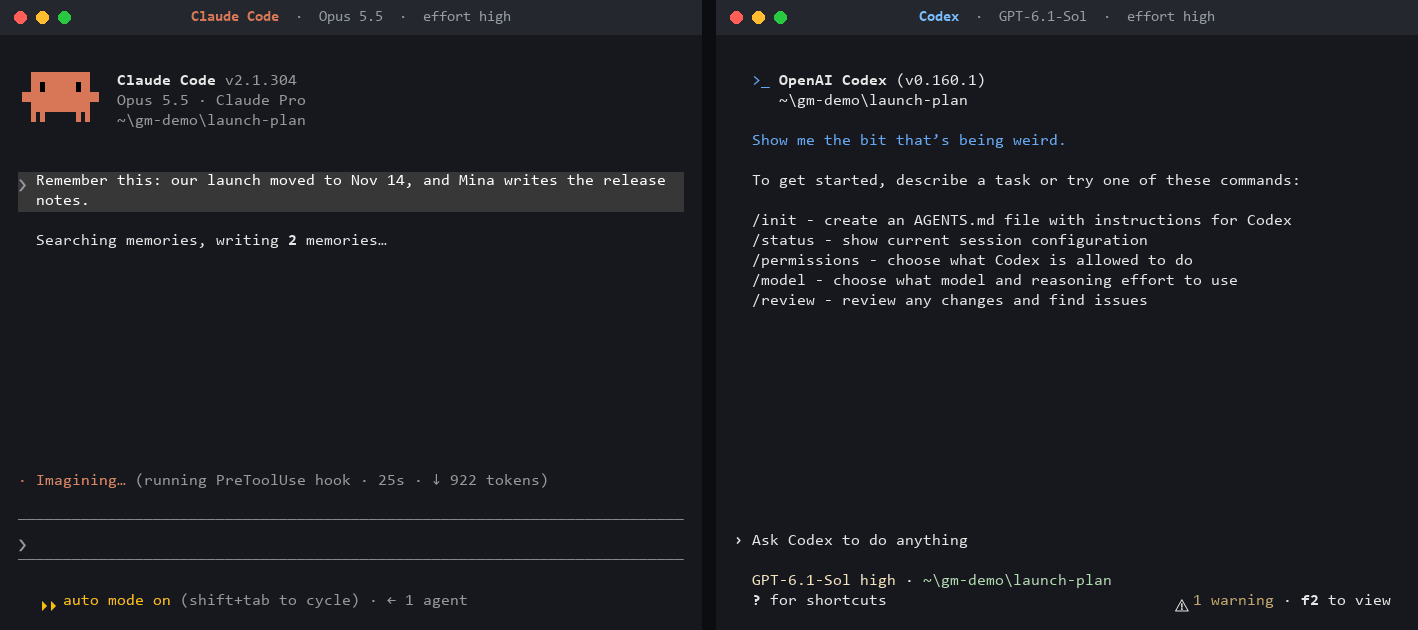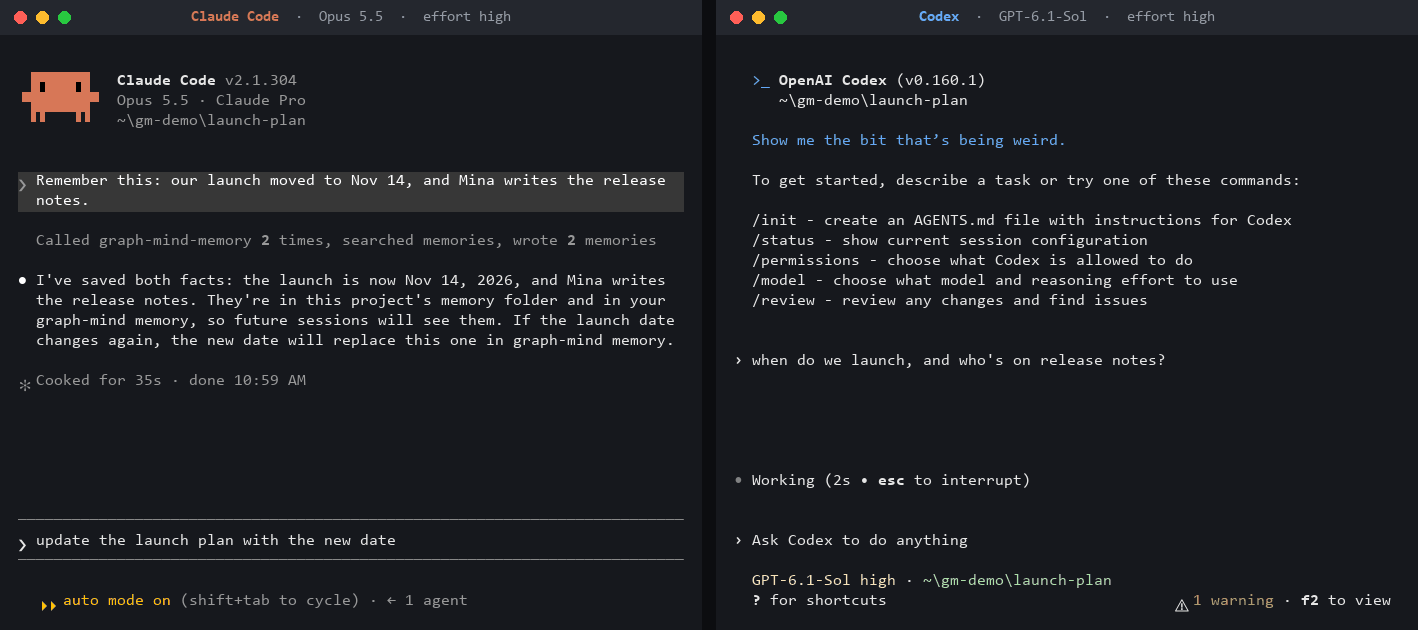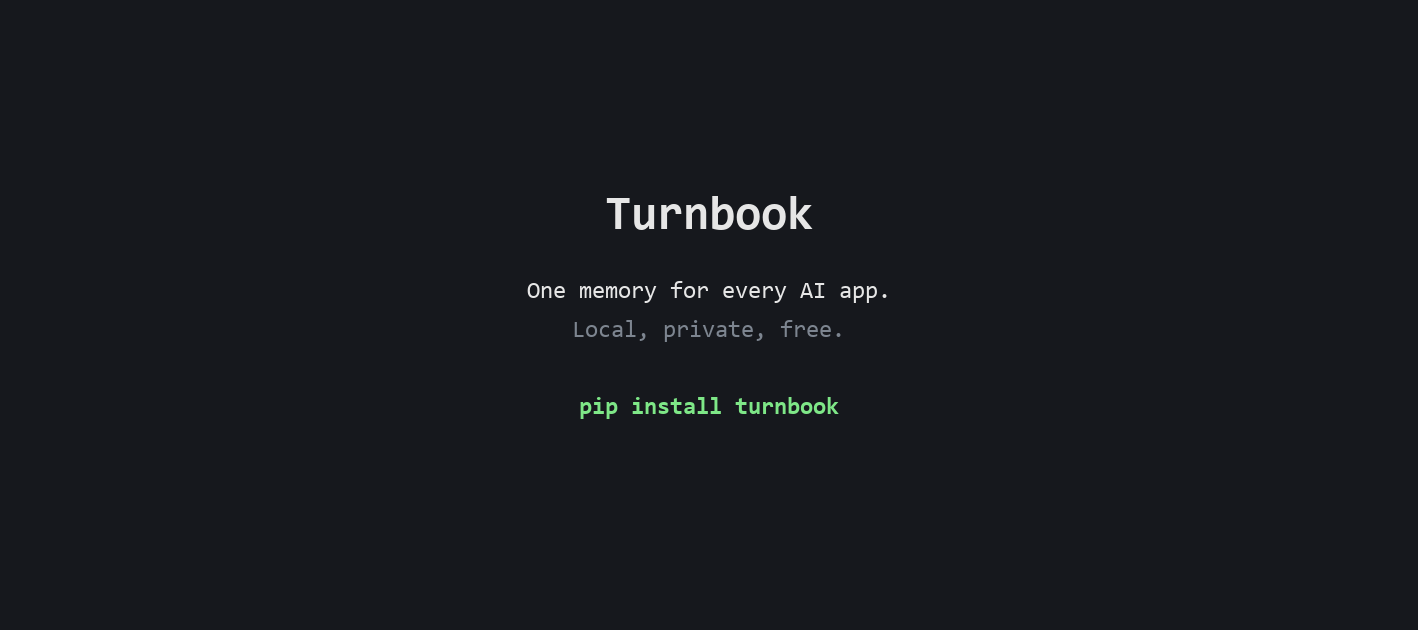
Recorded live on one PC: Claude Code (Opus 5.5, effort high) and Codex (GPT-6.1-Sol, effort high) sharing one Turnbook memory. Model thinking time is fast-forwarded.
If Turnbook saves you tokens or repeated explanations, a ⭐ helps other people find it.
Install
Windows: download Turnbook-Setup.cmd and double-click it, or in PowerShell:
irm https://raw.githubusercontent.com/goyohan0611-png/turnbook/main/scripts/install.ps1 | iexmacOS / Linux:
curl -LsSf https://raw.githubusercontent.com/goyohan0611-png/turnbook/main/scripts/install.sh | shNo Python needed; nothing else to set up. Restart your AI apps afterwards. Already have Python?
pip install turnbook && turnbook-install. Rather read the script and pin a version first?
Careful install.
Only Claude Code, and uv installed? It is also a plugin:
/plugin install turnbook --marketplace goyohan0611-png/turnbookCodex: codex plugin marketplace add goyohan0611-png/turnbook-plugin, then codex plugin add turnbook@turnbook.
Connecting an MCP client by hand
After pip install turnbook:
{
  "mcpServers": {
    "turnbook": {
      "command": "python",
      "args": ["-m", "turnbook.mcp_server"]
    }
  }
}
Claude Code: claude mcp add turnbook -- python -m turnbook.mcp_server. This gives the
tools only; turnbook-install also saves every conversation automatically.
Try it
Work as usual for a while, then open a new session, another app, or another model and ask:
- "Where did we leave off yesterday?"
- "Which database did we pick for the billing service, and why?"
- "What did you change in the auth middleware last week?"
- "What's my dog's name?" (any fact you mentioned once, in passing)
Nothing to tag or save by hand: every turn is already stored, and the agent pulls back the few that answer the question.
What it does
- Every agent, one memory. Claude Code, Codex, Cursor, Copilot CLI, Gemini CLI, OpenCode and any MCP app read and write the same memory. Decide with one, ask another; switch models, the memory stays.
- The right memory in every message. In Claude Code, Codex, Copilot CLI, Gemini CLI and OpenCode, Turnbook looks up what your message needs from the past and adds it before the model answers. Nothing to ask for.
- Free to save, on your PC. Every turn is stored word for word in one SQLite file: no model call, no tokens, no account, no cloud.
Everything else
- Made for orchestration. When an orchestrator runs several agents at once, they all write to the same memory as they work, so what one agent decided is there for the next. Every memory keeps which app and session it came from.
- Holds up as memory piles up. Grow a memory tenfold and the answer is still among the first 30 found for 92.7% of questions (92.6% before); a search takes about 0.1 s. As the memory grows
- Any language, across languages. The search model reads Korean almost as well as English: ask in Korean about something said in English, or the other way round. In Korean
- Your project's documents too.
turnbook docs add FOLDERkeeps its Markdown and text files searchable beside the conversations, section by section, and up to date as they change. - One memory across your PCs. Run
turnbook folder share, thenturnbook folder <code>on the other PC (the AI tells you the command; it never moves your memory by itself, so a web page cannot either). Office network or Tailscale, over TLS, every line encrypted before it leaves a PC. - Hand a memory to someone else as a file.
turnbook export FILEwrites all of it;--project FOLDERwrites only the conversations held in that folder. They runturnbook import FILE. - Yours. No account, no cloud of its own, no telemetry. Secrets are masked before anything is stored, and "delete the password I typed earlier" deletes it everywhere. docs/privacy.md
- Teams, if you want them. Share a project's decisions and progress with teammates' AIs, never your personal memory; files stay in Slack and GitHub. docs/teams.md
Works with
The installer finds these and connects them; run it again after installing a new one.
| app | conversations saved | how |
|---|---|---|
| Claude Code | every turn | reads its transcripts; a hook adds relevant memory to each message |
| Codex CLI | every turn | reads its transcripts; a hook adds relevant memory to each message (trust it once in /hooks) |
| Cursor | every turn | reads its transcripts |
| Copilot CLI | every turn | reads its transcripts; a hook adds relevant memory to each message |
| Claude Desktop (Cowork) | every turn | reads its session files |
| Gemini CLI | every turn | hooks; also adds relevant memory before each answer |
| OpenCode | every turn | plugin; also adds relevant memory before each answer, for any model |
| Claude Desktop chat, Windsurf, VS Code Copilot, Cline, LM Studio | what the model saves | MCP tools |
Any other MCP client works through the tools: see the hand-written config above.
How it works
flowchart LR
    A["Claude Code · Codex · Cursor<br/>Gemini CLI · OpenCode · ..."] -- "transcripts, hooks, plugin" --> C["capture service<br/>(runs in the background)"]
    C -- "verbatim turns,<br/>secrets masked" --> S[("your memory<br/>on this PC")]
    S --> I["local search<br/>words + meaning + time"]
    A -- "a question that needs the past" --> I
I -- "the few turns that answer it<br/>(a few thousand tokens)" --> A- Saving costs nothing. Turns are stored as they were said. No model summarises or extracts anything at write time, so nothing is lost or invented on the way in, and no tokens are spent.
- Search runs on your PC. Word search, a local embedding model (Google's EmbeddingGemma, 4-bit; ONNX, no GPU) and when things were said are combined, then ordered by a small learned score; the agent gets a short packet with the source turns, not a dump of history.
- The model you already use does the thinking. Turnbook hands it evidence; it answers. When models get better, the answers get better without changing the memory.
Beyond agent memory
Underneath, Turnbook is RAG over chat history with everything before the answer built in. A typical RAG stack is assembled from parts; Turnbook runs every step up to the answer on its own and leaves only the answer to the model you already use:
| Step | Typical RAG stack | Turnbook |
|---|---|---|
| Collect | an ingestion script you write | every turn saved automatically from your agents |
| Chunk | splitting rules to tune | one turn per entry, word for word |
| Embed | an embedding API, paid per token | a local model, free |
| Store | a vector database to run | one SQLite file |
| Retrieve | search code to write | words, meaning and time, re-ranked by a small learned score |
| Hand over | prompt-assembly code | a bounded evidence packet over MCP |
| Answer | your LLM | your LLM (Claude, Codex, ...) |
The same engine could serve a chatbot that remembers each of its users, a support bot that recalls past tickets, or a team's searchable decision log. Today it ships as a personal, local memory; a Python API and multi-user server mode are not built yet. Interested? Open an issue.
Does it work?
LongMemEval is the public benchmark for long-term chat memory: 500 questions over about 50 past sessions each. Turnbook's scores use gpt-5-mini as the answer model with the benchmark's own prompt and official gpt-4o judge; a question left unanswered counts as wrong.
| text the answer model reads (median) | accuracy | model tokens spent saving memory |
|---|---|---|
| 3.1k tokens (the default) | 91.8% (459/500) | 0 |
| 25k tokens | 93.0% (465/500) | 0 |
How it compares
Other memories publish their own LongMemEval scores, each with its own answer model, judge and setup, so they are not one ranking. The closest to like-for-like: Mastra's Observational Memory reports 94.9% with the same answer model, gpt-5-mini, which reads about 30k tokens of observations that gemini-2.5-flash wrote while the conversations were saved. It and others (Mem0, Supermemory) run an LLM over every conversation when saving it, writing dated facts and replacing outdated ones; that is where Turnbook loses points: 33 of its 41 misses are questions that combine several sessions, reason about dates, or need the newest value of something that changed. Turnbook keeps the original words, spends no model tokens saving them, and runs on your own PC.
What makes the difference
The learned re-ranker. Without it (plain rank fusion, no weight fitted on any benchmark): 87.0% of all 500, and 86.8% of the 380 questions never used for tuning, where the shipped search scores 91.1%. It helps most where answers are spread over several sessions. norerank
The memory added to each message (4 items, ~300 tokens) is a hint, not the full search: alone
it answers 61.4% of the same 500; brain_context, which the model calls for more, answers 91.8%.
It does not get in the way of unrelated work: on 200 GSM8K math problems with an unrelated
person's memory attached, gpt-5-mini solved 191, against 193 without it (p = 0.69).
hook ·
interference
As the memory grows
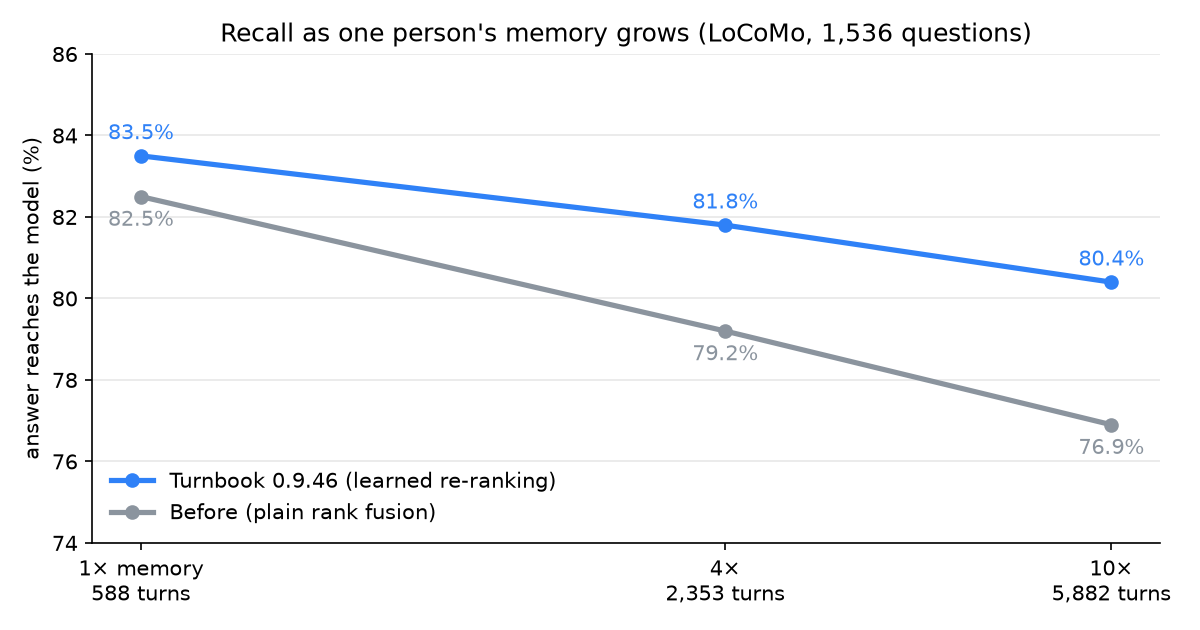
More past conversations means more that looks like the one you mean. On LoCoMo (1,536 questions), with each person's memory grown tenfold by storing other people's conversations beside it, the answer turn stays among the first 30 found for 92.7% of questions (92.6% before it grew); Turnbook with its re-ranker turned off drops from 90.2% to 88.4%. A search takes 30 ms at 5,882 turns and 116 ms at 55,882. Larger memories are being measured. scale
In Korean
Four LoCoMo conversations translated into Korean (582 questions). Search by meaning alone, share of questions whose answer turn is among the first 30 found: English 90.2%, Korean 86.9%, a Korean question about an English memory 87.8%. Word search finds "콩이" in "콩이를" (Korean particles). research/runs/graph-v9.21-korean
Every question, answer and verdict is in research/runs/; method, failures and
how to rerun it: docs/benchmarks.md.
FAQ
Will it slow my PC down? The background service uses about 2% of one CPU core when nothing new is coming in. An app's memory server holds about 525 MB. A memory search takes about 40 ms (46 ms at the 95th percentile on a GitHub runner); the first one after an app starts, about 1.4 s. Each new turn takes about 0.1 s to embed; the service runs below normal CPU priority and embeds backlogs at half pace. On a first install, the conversations already on the PC are read in the background while word search answers at once.
Which search model? EmbeddingGemma
(about 200 MB, downloaded from Hugging Face on first use). A memory from an older version is
read again with it in the background and moves over by itself. turnbook model shows which
model is in use; turnbook model REPO@FILE switches to any ONNX embedding model on Hugging Face (memory is read again with it in
the background). A model you picked is never deleted.
EmbeddingGemma is provided under the
Gemma Terms of Use; it is not part of Turnbook's own code
or license.
What does it cost? Nothing. No API key and no model calls of its own; your AI app reads a packet of a few thousand tokens when a question needs the past.
Does anything leave my PC? No, unless you share the memory with your own other PCs or a team. No telemetry. Secrets (API keys, passwords, card numbers...) are masked before storing.
How is this different from CLAUDE.md or an app's built-in memory? Those keep notes a model wrote, one app at a time. Turnbook keeps every turn as it was said and shares it across every app and model on the PC.
Korean? Yes: Korean and English conversations, and questions in either language. With the default model, search by meaning trails English by about 3 points in Korean, and a Korean question finds an English memory about as often: In Korean.
How do I remove it? turnbook-uninstall disconnects every app and stops the service; the
memory stays in ~/.turnbook unless you add --purge.
[!NOTE] Used daily on Windows. macOS and Linux pass every test in CI on every change, including an upgrade from the previous release, but have seen less daily use: issues are welcome.
More
MCP tools · See your memory in 3D
(turnbook-view) · Agent continuity prototype · Changelog · Security ·
Development: pip install -r requirements.txt, then python -m unittest discover -s tests
Contributions are welcome. License: Apache-2.0.
Pick your client and paste the snippet. Each one is the same server, written the way that client expects it.
- Run the command below in your terminal.
- Restart Claude Code, then check the connection with /mcp.
- Open your client's MCP config file, usually mcp.json.
- Merge this block into it.
- Restart the client to pick up the server.
- Run the command below in your terminal.
- Reload VS Code and check the MCP section of the Extensions view.
- Open ~/.codex/config.toml.
- Append this block.
- Restart Codex to pick up the server.
claude mcp add turnbook -- python -m turnbook.mcp_server{
"mcpServers": {
"turnbook": {
"args": [
"-m",
"turnbook.mcp_server"
],
"command": "python"
}
}
}code --add-mcp '{"name":"turnbook","args":["-m","turnbook.mcp_server"],"command":"python"}'[mcp_servers.turnbook]
command = "python"
args = ["-m", "turnbook.mcp_server"]Runs locally on your device. Your client starts the server itself, so nothing has to be hosted.
Install with your agent
Paste this prompt into your agent. It reads this page and does the setup for you.
Read https://aiagentslisting.com/mcp/graph-mind to learn what the "Graph Mind" MCP server does and how to install it. Add it to my coding agent's MCP configuration as documented on that page, then confirm the server connects and list the tools it exposes.Agents can also browse this directory over MCP at https://aiagentslisting.com/api/mcp
This server runs locally, so we can't read its tool list over the web yet.
We could not run this server: it ships no npx package for our sandbox and no public endpoint. The four checks that need a live server are left out, and the grade tops out at B until one exists.
What's missing
- Claimed by ownerThe maintainer proved ownership of this listing.0/4
All 5 checks (4 passed)
- Installation methodRequiredThe README documents at least one way to install or connect.15/15
- Has a READMERequiredThe repository ships documentation we could read.10/10
- Easy installA paste-ready client config (an mcpServers block) is documented.12/12
- Has a licenseThe repository declares a license.8/8
- Claimed by ownerThe maintainer proved ownership of this listing.0/4
- Verified liveNot checkableWe connected to the server and it answered a real MCP handshake.—
- Exposes toolsNot checkableThe server reports at least one tool, from its manifest or a live read.—
- Ships promptsNot checkableThe server exposes at least one prompt template.—
- Ships resourcesNot checkableThe server exposes at least one resource.—
Maintain this server? Claiming proves you own the listing and earns the last 4 points.
Claim this listingShow this grade in your README

Paste this line near the top of your repository's README. The badge always renders the current score.
[](https://aiagentslisting.com/mcp/graph-mind)Alternatives to Graph Mind
Nothing comparable is listed yet.
v1.1.01.1.0Release notesv1.0.01.0.0Release notesv0.10.50.10.5Release notesv0.10.40.10.4Release notesv0.10.30.10.3Release notesv0.10.20.10.2Release notesv0.10.10.10.1Release notesv0.10.00.10.0Release notesv0.9.480.9.48Release notesv0.9.470.9.47Release notesv0.9.460.9.46Release notesv0.9.450.9.45Release notesv0.9.440.9.44 — Graph-MIND is now TurnbookRelease notesv0.9.430.9.43Release notesv0.9.420.9.42Release notesv0.9.410.9.41Release notesv0.9.400.9.40Release notesv0.9.390.9.39Release notesv0.9.380.9.38Release notesv0.9.370.9.37Release notes
Send this prompt to your agent to leave a review
Connect to the AI Agents Listing MCP server at https://aiagentslisting.com/api/mcp using the HTTP transport and complete the sign-in when it asks. Then call the submit_review tool for the listing "graph-mind" with a rating from 1 to 5 and a short note on what worked and what did not.No reviews yet
Be the first to share your experience with this tool.
Subscribe to our newsletter
One email a week. New agents, MCP servers and skills, and what is actually getting traction.